Platform
One platform for the whole inference lifecycle, from the kernel to the invoice.
Metrale is three layers that share one request path. The engine makes the GPUs faster, the control plane keeps the fleet honest, and the economics layer turns what they report into numbers finance can sign.
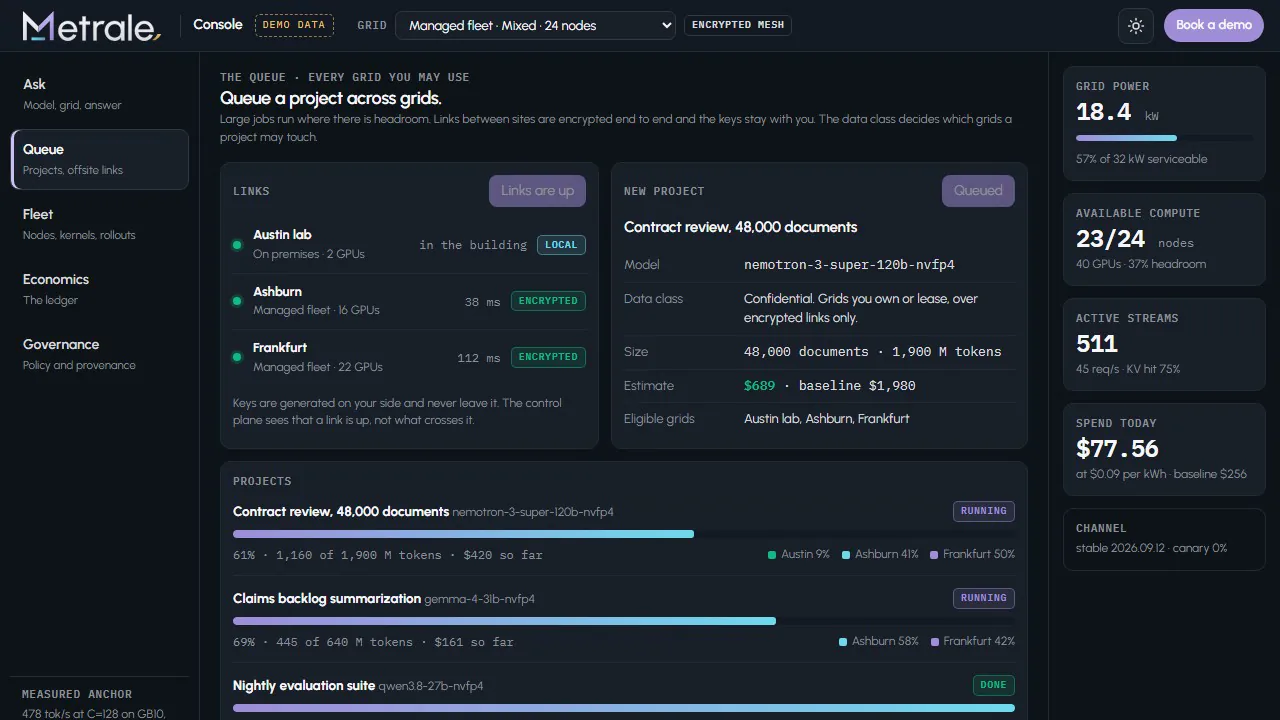
Metrale Console. Demo data, recorded from the product mockup.
The products
Inference layer
Metrale Engine
Compiled per hardware, model and quantization. More tokens per GPU, verified on the box before it ships.
Explore →Governance and control plane
Metrale Control
Signed recipes, canary rollouts, GPU aware routing, autoscaling, node repair and policy. Never on the request path.
Explore →Economics layer
Metrale Economics
Cost per workload, chargeback, stranded capacity and payback, against the baseline you ran before.
Explore →Posture
Security
One signed binary, no interpreter in the request path, links designed for a hostile network, nothing leaves.
Explore →Surfaces
Deployment
Hosted with private connectivity, your cloud account, on premises or air gapped. Same binary, same recipes.
Explore →Compatibility
Hardware and models
Verified silicon, targets in bring up, and every model recipe we ship, generated from the repository.
Explore →Architecture
One request path. One ledger.
Deployment surfaces
Private datacenters, AWS, Azure, GCP and neocloud GPU pools. Hosted with private connectivity where you want us to run it, bring your own cloud where you do not.
- Private datacenter
- Air gapped network
- AWS
- Azure
- GCP
- Neocloud GPU pools
- Workstation and edge
Started on a single box. Built to run a fleet.
Metrale began as local inference on a DGX Spark. The same pinned stack scales to datacenter GPU fleets with the qualification record, routing and observability that enterprises need in production.
Next step
See the platform on your workload.
A working session with the console, the ladder and the payback model, on demo data or yours.